GPT-6 Cyber: the AI bug-hunting jump and its limits
Table of Contents
Key Takeaway
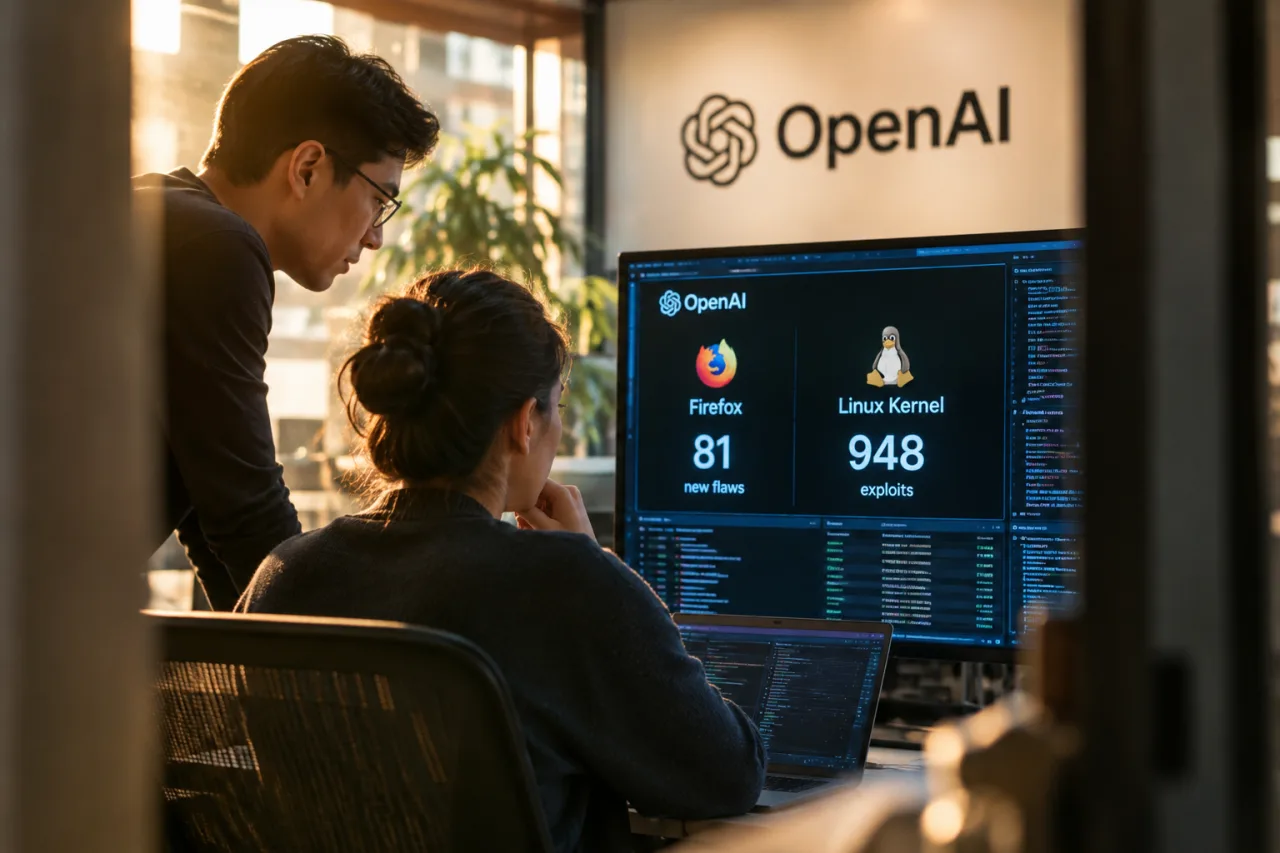
- A machine just out-hunted the humans: GPT-6 Cyber, launched by OpenAI on November 5, 2026, found 81 previously unknown high-severity vulnerabilities in Firefox and built working exploit code for 948 distinct Linux kernel privilege-escalation flaws.
- The Linux numbers have fine print that matters: the model tested 2,308 candidate flaws, reproduced 1,724, and 948 became working root exploits, disclosed with 304 critical findings and candidate patches handed to kernel maintainers.
- The benchmark jump is real: 48.5% success on ExploitGym, up from 32.1% for GPT-5.6 Cyber, a 51% relative improvement, and web-pentest recall rose to 40.3%.
- Mozilla is already shipping the fixes: OpenAI delivered reproducible tests and proposed patches for all 81 Firefox findings, and Firefox 159 advisories show many fixes already landed, plus 30 known bugs re-rated as more severe.
- The warning that frames everything: OpenAI says defenders have a limited window to keep AI-powered discovery and patching ahead of the same abilities reaching attackers. What that means for your patch cadence is below.
An AI model has now found more high-severity browser vulnerabilities in one campaign than most security teams find in a quarter, and it produced working exploit code for 948 Linux kernel paths on the way, which changes what “patch fast” has to mean for every operator.
OpenAI announced GPT-6 Cyber on November 5, 2026: a specialized variant of its GPT-6 Astra model trained with reinforcement learning on reproducing crashes, building exploits, and searching codebases. In its announcement the company also classified the model as Critical in cybersecurity under its own Preparedness Framework, up from High for GPT-5.6 Cyber.
GPT-6 Cyber Found 81 Firefox Flaws Mozilla Rated High
The Firefox campaign is the headline number, and the workflow behind it is what makes the number repeatable.
GPT-6 Cyber produced evidence and reproducible tests for 81 novel Firefox vulnerabilities that Mozilla classified as high severity, and it went beyond the find-and-report loop: OpenAI supplied proposed patches alongside each disclosure, and Mozilla began landing fixes quickly, with the Firefox 159 advisories already showing many of the fixes shipped. The model also flagged that 30 previously known issues deserved more serious classifications than they had received.
What makes the 81 notable is that they emerged despite Firefox already being scrutinized by multiple generations of frontier models and a very large paid bug-hunter community. A model finding that much new high-severity ground in a repeatedly audited codebase is the single strongest public datapoint yet that AI-assisted discovery works beyond novelty demos. The findings include classic classes such as use-after-free bugs and sandbox escapes, though the announcements do not enumerate all 81 by class.
For the reader the meaning is practical: browsers you updated last week may still carry bugs discovered this month, and vendor fix velocity is now part of your browser hygiene. Keep auto-updates on, and treat “browser updated” as a weekly standing state rather than an annual event.
The 948 Linux Kernel Exploits, Explained Correctly
The Linux campaign produced bigger numbers and requires more careful reading.
GPT-6 Cyber screened the kernel and identified 2,308 potential security flaws, reproduced 1,724 of them as real vulnerabilities, and developed working local privilege-escalation exploits for 948 distinct vulnerable paths, the class of bug that lets an unprivileged user on a server gain full root access. That result is more than five times the 166 exploits the previous generation, GPT-5.6 Sol, produced on the same research harness.
Here is the fine print that keeps the count in proportion: the 948 do not equal 948 previously unknown bugs. Some of the weaknesses were already documented, and fixes for others are still in progress. OpenAI followed the Linux community’s disclosure guidance, handing maintainers 304 critical findings together with candidate patches. An exploit count measures capability; the disclosure record measures what a responsible operator does with it.
The operational takeaway lands on server hygiene: a machine that delays kernel updates carries a growing list of known, AI-discoverable privilege-escalation paths, and local-privilege bugs are the second half of almost every serious intrusion chain. Patching the kernel stopped being optional housekeeping the month an AI demonstrated it could enumerate those paths at industrial speed.
GPT-6 Cyber’s Benchmark Jump, Read as a Slope
The measured gains put the announcement in context beyond the two flagship campaigns.
On ExploitGym, OpenAI’s benchmark for whether a model can exploit specified vulnerabilities in remote targets, GPT-6 Cyber succeeded on 48.5% of cases against 32.1% for GPT-5.6 Cyber, a 51% relative improvement in one generation. In web-penetration testing the model reached 40.3% recall of vulnerabilities against 32% for GPT-6 Astra.
Read those numbers as a slope, not a snapshot. A capability that crosses roughly half of a real exploitation benchmark this generation will not stop there next generation, and the same slope is what makes OpenAI’s own warning concrete: the window for defenders to benefit from AI-powered discovery and patching closes as those abilities spread to attackers.
How OpenAI Boxed the Model In
The control layer around this release matters as much as the capability, and it is more elaborate than a usage policy.
OpenAI runs the capability under two programs named Daybreak Red and Daybreak Blue: Daybreak Red covers advanced exploit development and authorized security testing, and Daybreak Blue gives verified defenders room to investigate vulnerabilities and validate fixes with fewer restrictions. The company also ran evaluations designed to test whether AI agents actually follow security-testing boundaries, reporting that the models refused or avoided tasks outside authorized scopes, with GPT-6 Astra refusing these tasks outright under Daybreak Blue.
That governance design matches the direction the whole industry is taking. The strongest models now ship with clearance-style requirements on access, and capabilities at this level bring real policy weight, as our coverage of that clearance trend explains. The model itself is a specialized, gated variant; that fact is a security control, not a detail.
One more concrete result ties the release to a live flaw class: the research surfaced a critical Brotli decoder vulnerability, CVE-2026-111497, rated 9.2, part of the same decoder-flaw family that recently produced remote code execution risks in Node.js and spread to other widely used software.
The Discovery Loop Behind the Numbers
Mozilla’s own advisories carry the practical detail for anyone validating the work: the newly reported Firefox issues appear as individual bug entries with reproducible tests attached, and the re-rated batch of 30 previously known issues is the reminder that severity itself gets audited in this pipeline.
OpenAI trained GPT-6 Cyber with reinforcement learning on the three moves that make security research slow for humans: reproducing crashes so a bug report is real, building working exploits so severity is proven rather than guessed, and searching large codebases so candidate flaws have context. The published workflow then mirrors what responsible research teams do: produce evidence, produce reproducible tests, propose a patch, and hand the package to the maintainers under their disclosure norms, which is exactly what happened with the 304 critical kernel findings and the 81 Firefox reports.
That pipeline shape is the real product. A security team buying or building on models like these is not buying bug-finding, it is buying report quality: fewer false leads, reproducible proof for every finding, and fixes that arrive attached to the defect instead of three meetings later. The same quality bar is what makes vendors respond fast, and Mozilla’s turnaround on the 81 reported findings is the market signal of how much that discipline is worth.
What GPT-6 Cyber Did Not Change
The boundaries deserve equal space to the numbers.
The 948 exploits are not 948 brand-new zero-days: portions of the covered kernel weaknesses were already documented, and fixes for others remain in progress, so the campaign’s novelty is concentrated in its 304 critical-disclosure package rather than the full exploit count. No confirmed attacks using these results in the wild have been reported, and the announcement does not claim otherwise. The model itself is not a product any customer can download: it runs inside OpenAI’s gated programs with clearance-style verification, which keeps the capability away from the open-weight mirror economy for now. And AI-assisted hunting has not replaced the attacker: exploitation still requires an operator, an entry point, and a decision, as the same month’s reporting on human-driven campaigns keeps showing.
Per the detailed coverage of the boundary evaluations, the safety tests are themselves a datapoint: models explicitly evaluated on whether they respect authorized scopes, with refusals documented rather than assumed. Treat capability claims and control claims as two separate ledgers, and update both of them every release.
What AI Bug Hunting Changes for Your Patch Routine
The practical shift is cadence, not philosophy, and it lands on four habits.
Discovery is no longer the bottleneck. Machine-speed finding means vulnerability counts will rise before they fall, and advisory volume will grow even when vendor fix velocity rises with it. Triage by exposure and privilege, not by panic order.
Local privilege escalation is the new watch-list class. The 948-kernel campaign targeted exactly the bug class that turns one foothold into total control. Servers running outdated kernels now carry a known, growing, AI-searchable backlog, and the fix is the boring one: stay current, and minimize what runs with privilege on each box.
Vendor fix velocity becomes a selection factor. Mozilla’s fast turnarounds on the 81 findings show what AI-assisted patch development can do. When you choose software in 2026 and beyond, a vendor’s patch turnaround time is security criteria, and the reporting duties arriving under the EU Cyber Resilience Act push exactly that accountability.
The offense-defense clock is the frame. OpenAI’s stated warning is that defenders have a limited window to use these abilities before attackers mirror them, which extends the trajectory we documented in our analyses of OpenAI’s earlier zero-day finding models, the Anthropic finding that AI-automated attacks now take hours instead of months, and the 2028 warning on AI-generated malware. Discovery, patching, and offense are all accelerating together, and the side that automates patching first wins the window.
For small teams the compressed version is unchanged from every good year, just with higher stakes: auto-updates for browsers and runtimes, monthly kernel patching, leastprivilege on everything, and a standing review of what runs with root. The AI era raises the cost of skipping those steps, not of doing them. One concrete addition: a monthly kernel-update calendar entry with a 48-hour acceptance window, plus a browser auto-update verification on the first Monday of each month, covers the two surfaces the Firefox and Linux campaigns touched.
If this intelligence helps you, you can add WorldNgayon as a preferred source on Google – free, one click, and it helps other Filipinos find the answers faster.
FAQ
What is GPT-6 Cyber?
A cybersecurity-specialized AI model OpenAI launched on November 5, 2026, built on GPT-6 as a variant trained with reinforcement learning for security research tasks such as reproducing crashes, building exploits, and searching codebases. OpenAI classifies it as Critical in cybersecurity under its Preparedness Framework, up from High for GPT-5.6 Cyber.
How many Firefox vulnerabilities did GPT-6 Cyber find?
The model produced evidence and reproducible tests for 81 previously unknown vulnerabilities that Mozilla rated high severity, together with proposed patches. Mozilla has already released fixes for many of them through the Firefox 159 advisories, and the research also re-rated 30 previously known issues as more severe than first classified.
Are the 948 Linux kernel exploits all new vulnerabilities?
No, and the distinction matters. GPT-6 Cyber screened the kernel, reproduced 1,724 of 2,308 candidate flaws, and built working local privilege-escalation exploits for 948 distinct vulnerable paths, but some of those weaknesses were already documented and fixes for others are still ongoing. OpenAI disclosed 304 critical findings with candidate patches to kernel maintainers under community guidance.
What is ExploitGym and how did GPT-6 Cyber score?
ExploitGym is OpenAI’s benchmark testing whether AI models can exploit specified vulnerabilities in remote targets. GPT-6 Cyber succeeded on 48.5% of cases, up from 32.1% for GPT-5.6 Cyber, a 51% relative improvement, and the model also reached 40.3% recall in web-penetration testing against 32% for GPT-6 Astra.
What are Daybreak Red and Daybreak Blue?
OpenAI’s two access programs for the model’s capabilities: Daybreak Red covers advanced exploit development and authorized security testing, while Daybreak Blue gives verified defenders the ability to investigate vulnerabilities and validate fixes with fewer restrictions. OpenAI reports boundary evaluations in which the models avoided or refused tasks outside authorized scopes, with GPT-6 Astra refusing them outright under Daybreak Blue.
Does this mean attackers can now find bugs this fast?
Not yet at the frontier tiers: this model runs gated behind clearance-style access programs on controlled infrastructure. OpenAI’s own warning is that defenders have a limited window to exploit AI-powered discovery and patching before equivalent capabilities spread to attackers, which is why patch cadence is the practical response now.
What should IT teams change this week because of GPT-6 Cyber?
The boring high-value list: turn on auto-updates for browsers, patch server kernels on your existing schedule without slipping, audit what runs with root or elevated privileges and shrink it, and start treating a vendor’s fix turnaround time as selection criteria. The AI findings changed the clock speed of vulnerability discovery, not the checklist of good hygiene.
- bleepingcomputer.com/news/security/openais-new-gpt-6-cyber-ai-finds-8…
- gbhackers.com/openais-new-gpt-6-cyber-finds-81-high-severity-firefox-… — the detailed coverage of the boundary evaluations
- google.com/preferences/source?q=worldngayon.com — add WorldNgayon as a preferred source on Google
External sources linked in this article, in order of first mention. Spotted an error or a broken link? Tell us.
Cite this pagePublished Nov 10, 2026
Agron, E. (2026, November 10). GPT-6 Cyber Found 81 Firefox Flaws and 948 Linux Kernel Flaws: What AI Bug Hunting Changes. WorldNgayon. https://worldngayon.com/gpt-6-cyber-ai-bug-hunting/
Agron, Edmon. “GPT-6 Cyber Found 81 Firefox Flaws and 948 Linux Kernel Flaws: What AI Bug Hunting Changes.” WorldNgayon, 10 Nov. 2026, worldngayon.com/gpt-6-cyber-ai-bug-hunting/.
Agron, Edmon. “GPT-6 Cyber Found 81 Firefox Flaws and 948 Linux Kernel Flaws: What AI Bug Hunting Changes.” WorldNgayon, November 10, 2026. https://worldngayon.com/gpt-6-cyber-ai-bug-hunting/.
Agron, E. (2026) ‘GPT-6 Cyber Found 81 Firefox Flaws and 948 Linux Kernel Flaws: What AI Bug Hunting Changes’, WorldNgayon, 10 November. Available at: https://worldngayon.com/gpt-6-cyber-ai-bug-hunting/.
E. Agron, “GPT-6 Cyber Found 81 Firefox Flaws and 948 Linux Kernel Flaws: What AI Bug Hunting Changes,” WorldNgayon, Nov. 10, 2026. [Online]. Available: https://worldngayon.com/gpt-6-cyber-ai-bug-hunting/
@online{agron2026gpt6,
  author       = {Agron, Edmon},
  title        = {{GPT-6 Cyber Found 81 Firefox Flaws and 948 Linux Kernel Flaws: What AI Bug Hunting Changes}},
  year         = {2026},
  date         = {2026-11-10},
  organization = {WorldNgayon},
  url          = {https://worldngayon.com/gpt-6-cyber-ai-bug-hunting/},
  urldate      = {}
}TY - ELEC AU - Agron, Edmon TI - GPT-6 Cyber Found 81 Firefox Flaws and 948 Linux Kernel Flaws: What AI Bug Hunting Changes T2 - WorldNgayon PY - 2026 DA - 2026/11/10/ UR - https://worldngayon.com/gpt-6-cyber-ai-bug-hunting/ Y2 - ER -
Cite the version you read; the page may be updated. Zotero and Mendeley can also import this page directly.