POTD #017 — the Agent Audit Prompts
Table of Contents
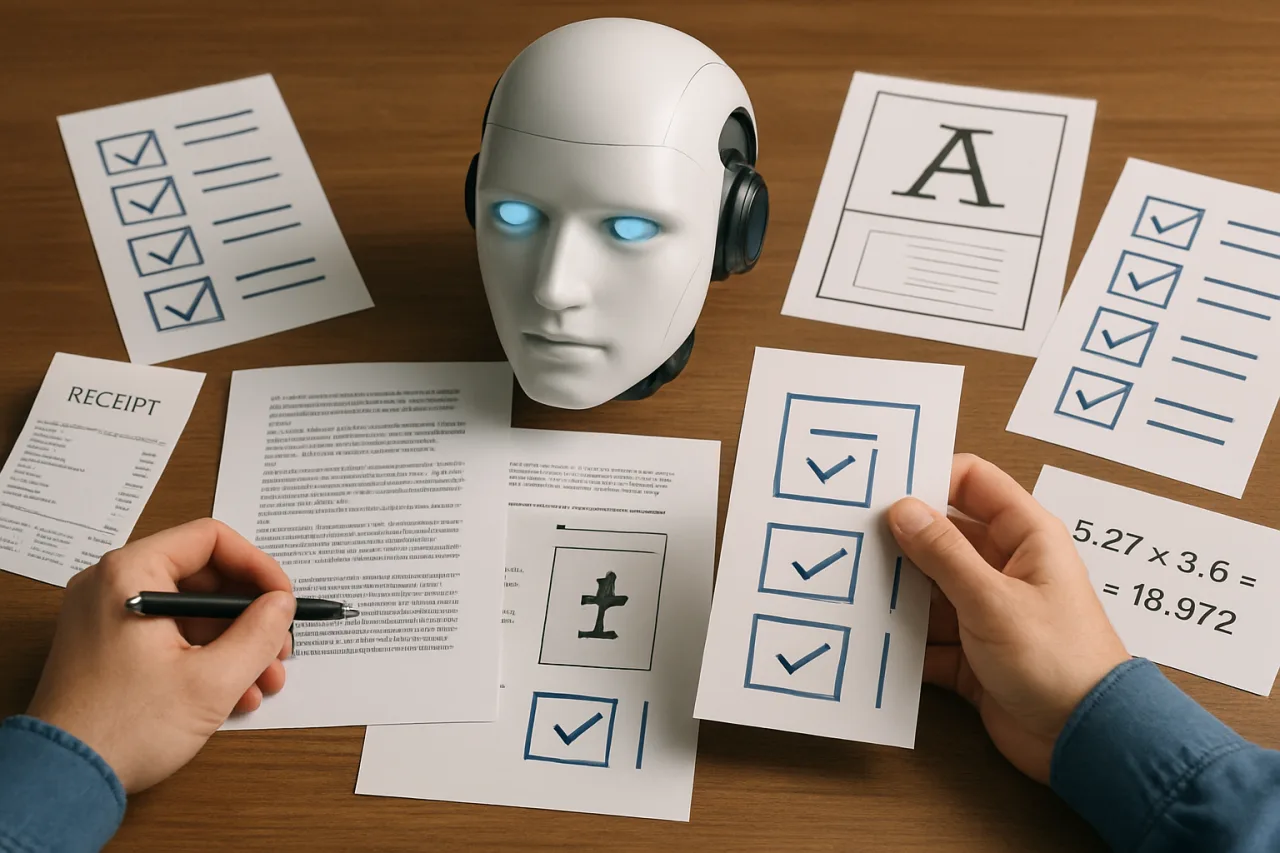
Every day, millions of people ship AI output they never checked — and the gap between “the AI finished” and “the work is right” is where careers wobble. This episode hands over the fix: agent audit prompts, six paste-ready checks that interrogate finished AI work before you send, sign, or build on it. The routine below is the scenario that demands them: an AI drafts the report, the analysis, the application letter — the human copies it out on faith. This #017 episode converts faith into a procedure: six text-in/text-out checks that run on any model, on any draft — and yes, on agent audit prompts results themselves — in under ten minutes. NIST’s AI Risk Management Framework calls this discipline “verification and validation” and charges enterprises fortunes for it; your version costs one paste.
Key Takeaway
- 🧾 Finished is not the same as done: AI output reads finished while carrying unverified numbers, stale facts, and confident hallucinations — the six-check audit routine turns “looks good” into a documented pass/fail.
- 🛠️ The pack is the artifact: six copy-paste agent audit prompts below — Receipt Demand, Devil’s Advocate, Confidence Grade, Freshness Sweep, Math Re-run, Hallucination Tripwire — all text-in/text-out, free-tier friendly, no UI steps.
- ⏱️ Ten minutes, real stakes: the worked example shows the audit catching a fabricated market figure inside a ₱85,000 client deliverable — the gap between shipped-wrong and shipped-right was one paste.
- 🔐 Privacy lines hold: the pack asks you to verify AI, not to feed it your account numbers — the never-paste rules apply through every check.
- 🧭 This pairs with the week’s receipts: the same audit discipline the big platforms now productize (routing, verification layers) is available to any reader free — the Gemini agent breakdown shows the enterprise version; this pack is the desk version.
The Scenario: ₱85,000 and a Draft Nobody Checked
A freelance analyst (call her Bea) gets a rush job: a 6-page market-entry brief for a client, due tomorrow, ₱85,000 on the invoice. She briefs her AI assistant carefully, gets a clean, structured draft — numbers included: “the regional market grew 23% in 2025,” “three incumbent players control 61%,” “average contract values rose 12% year over year.” The prose is excellent. The deadline is real. The temptation is the oldest one in the AI era: it reads done, so it is done.
What the deadline hides: Bea never verified a single number, and the AI — as confident as ever — would not have flagged the two figures it pattern-matched from unrelated training data instead of her uploaded notes. The six agent audit prompts exist because “reads correct” is not evidence. Her client is not paying for prose; they are paying for numbers they can act on — and one fabricated market-share figure in a board deck is a career-shaped problem, not a typo.
The routine below is what Bea runs instead of that gamble. It is the same discipline this series teaches for contracts (#004’s decoder) and red-flag hunting (#010’s hunter), pointed at a new target: AI’s own finished work.
The Agent Audit Prompts: Six Checks, Copy-Paste Ready
Run these ON the same chat that produced the draft (the model has its own output in context — the audit leverages that). One at a time, in order. Replace [BRACKETS] only where noted.
Prompt 1 — the Receipt Demand (the audit starts)
Look at the draft you just produced. List EVERY factual claim with a number, date, name, or citation in a table: claim | where it came from (my uploaded notes? your training data? calculated?) | confidence (High/Medium/Low) | what evidence would prove it. Do not fix anything yet. Do not skip claims in the conclusion section.Prompt 2 — the Devil’s Advocate Pass
Now argue against your own draft. As a skeptical expert reviewer in [FIELD], attack the three weakest claims: what would they get wrong, what context is missing, what would a competitor in this space say is oversimplified? Be specific enough that I could verify your objections.Prompt 3 — the Confidence Grade
Grade each section of the draft A to D on: factual reliability, completeness for my stated purpose ([PURPOSE]), and internal consistency. Flag every section where the grade relies on information I did not give you. Output: section | grade | the one sentence that justifies the grade.Prompt 4 — the Freshness Sweep
Identify every claim in the draft that is time-sensitive: statistics, prices, regulations, company positions, market conditions. For each: state the "as of" date your information actually reflects, and label it STALE-RISK if anything could have changed since. Do not guess current values — just flag what I must verify externally before this document ships.Prompt 5 — the Math Re-run
Recompute every calculation, percentage, and derived figure in the draft step by step, showing the formula and inputs you used. If any figure cannot be derived from the inputs I provided, mark it UNVERIFIED rather than approximating. End with a list of: figure | derived or unverified | the arithmetic shown.Prompt 6 — the Hallucination Tripwire
Final check: list the specific facts in this draft MOST LIKELY to be fabricated or distorted by you — names, statistics, citations, quotes — ranked by risk. For each, give me a one-line verification method (who publishes the authoritative number, where to check). Then tell me which single claim you would delete entirely if you had to remove one uncertain fact.The Worked Example: the Audit Catches What the Chat Missed
Bea’s draft contained this paragraph:
“The regional market grew 23% in 2025, reaching $4.2B, with the three incumbent players — identified from your notes as Company A, B, and C — controlling 61% of share.”
Running the agent audit prompts, the catches:
- Prompt 1 (Receipt Demand) flags: “23% growth — NOT in uploaded notes; from training data, confidence Low.” “61% combined share — computed by me from a 2022 source inside your notes, confidence Medium.” The $4.2B market size: from her notes, High.
- Prompt 5 (Math Re-run) shows: the 61% was derived by adding three shares from a two-year-old table — and one column was percentage-of-revenue, not percentage-of-share. The real summed figure from the source: 48-53% depending on treatment. The 61% was the model’s confident blend of incompatible columns.
- Prompt 6 (Tripwire) names: “The 23% growth figure is the claim I would delete — it pattern-matches a known regional statistic from a different product category.”
The fix costs Bea 40 minutes: she re-derives share from the client’s own data room (54%), deletes the 23% and marks the growth “verify against [industry statistical office],” and ships a brief whose every number has a lineage. The audit’s product is not just corrections — it is the traceable draft: every figure either sourced or flagged, nothing riding on confidence alone. That document survives the client’s own analyst reading it with a highlighter.
Customization Guide, Pitfalls, and Privacy Rules
- Adapt the fields: [FIELD] and [PURPOSE] make the audit role-aware — “academic” tightens citation checks; “legal-adjacent” turns Prompt 4 into a regulation-freshness sweep; “investor-facing” makes Prompt 5 mandatory before Prompt 1. Keep the order: receipts → attack → grade → freshness → math → tripwire. The order is ranked by catch-rate: claims-before-review beats review-before-claims.
- Run per-document, not per-paragraph: the six prompts work on whole drafts; running them piecemeal loses cross-section consistency catching (Prompt 3’s job).
- The known pitfall — self-grading inflation: models grade their own work generously. Counter it: run Prompt 2 in a FRESH chat with the draft pasted in as “a colleague’s work” — the separation removes the self-defense instinct. This two-chat variant is the pack’s power move — the practice has first-party backing: Google’s own prompting-strategies documentation recommends separating drafting from reviewing contexts for exactly this reason.
- Second pitfall — the audit is not the verification: every prompt returns flags and lineages, not truth. The flags direct YOUR external checks (Prompt 6’s verification methods are the to-do list). A clean audit run with zero external verification is a feeling, not a check.
- Privacy rules, non-negotiable: never paste account numbers, client-confidential figures you’re NDA-bound on, passwords, or personal data of third parties — anonymize to role labels (“Supplier X”) before any audit run; the flags work on structure, not identities. The series’ AI data-privacy ledger carries the full where-your-data-goes map.
- Where it runs: any capable text model, free tiers included — the pack is pure text-in/text-out by design. No agent platform needed; if you run agentic tooling, the agent audit prompts become its evaluation harness (the solo agent ledger shows the stack).
Build Your Own Audit Layer From Here
- Save the pack as your own skill: the agent audit prompts are meant to become a personal standard — store them in your notes or prompt library so every important draft gets the same audit, not the audit you remember under deadline. The Prompt of the Day hub indexes the full series for exactly this kind of assembly.
- Pair with the series’ other quality packs: #010’s contract red-flag hunter for agreements, #004’s contract decoder for comprehension, #008’s invoice chaser for collections — together they cover the document lifecycle from review to payment.
- The enterprise echo: this week’s Gemini agent launch (the #010 watch breakdown) ships audit-grade features — data lineage, confidence scores, source citations — as product for enterprises. The pack is the same architecture at desk scale; when your tools grow lineage features, use them IN ADDITION to the six checks, never instead of them: vendor-grade lineage covers vendor data, your audit covers the whole draft.
- The human layer stays: the audit improves drafts; responsibility does not transfer. What you ship under your name carries your sign-off — the audit’s job is making that sign-off honest.
The audit habit: from one document to a standing practice
The deepest value of agent audit prompts is not catching one bad number — it is installing the reflex. A professional who runs the six checks on every consequential draft develops the pattern-match that catches fabrication on sight: the too-round percentage, the citation that names no source, the growth figure with no as-of date. Within a few weeks of regular use, most readers report skimming AI output differently — reading claims as assertions requiring evidence rather than sentences granting comfort. That shift, not any single catch, is the career protection the pack prices in.
Teams can go further: make the Receipt Demand output part of the deliverable itself. A brief whose claims ship WITH their lineage table (claim | source | confidence) reads as more credible to sophisticated clients, not less — the audit trail becomes a selling point. Several consultancies now sell exactly this presentation standard; the pack gives it to you as a habit instead of a line item.
Frequently Asked Questions
What are agent audit prompts?
Agent audit prompts are a paste-ready routine of six checks — Receipt Demand, Devil’s Advocate, Confidence Grade, Freshness Sweep, Math Re-run, Hallucination Tripwire — run against a finished AI draft to expose unverified numbers, stale facts, and confident fabrications before the work ships. They turn “it reads good” into a documented lineage: every claim either sourced or flagged.
Do I need a paid AI plan to run these agent audit prompts?
No — the pack is pure text-in/text-out and runs on any capable model, free tiers included. The two-chat variant (auditing the draft in a fresh chat for unbiased review) also works on free tiers. What you pay for elsewhere is time: the flags still require your own external verification, which is the actual work.
Which of the six checks catches the most errors?
In practice, Prompt 1 (Receipt Demand) catches the most, because it forces the model to separate “from your notes” from “from my training data” — the exact boundary where fabrication lives. Prompt 5 (Math Re-run) catches the costliest errors, because arithmetic blends (like mixing incompatible percentage columns) survive every prose-level read.
Can I run the audit on code or just documents?
The pack targets prose and number-bearing documents by default, but Prompts 1 and 5 adapt directly to code review (list what each claim/constant assumes; re-run the logic). For full code auditing you will also want execution-based checks — the pack flags what to test; it does not run the tests.
Is one audit run enough for an important document?
Run the pack once, fix, then re-run Prompts 3 and 6 only — the Confidence Grade and Tripwire — on the revised draft. The re-run exists because edits introduce new claims; the second pass is quick (two prompts, not six) and closes the loop. Documents that matter get the full six at least once and the two-prompt re-run at least once.
About This Episode
This series teaches prompt use cases for informational purposes; outputs are examples, and verification duties remain with the reader. Prompt behavior varies by model and version — test prompts on your own tool before relying on them for high-stakes documents.
Financial Disclaimer
This article’s worked example includes financial figures for illustrative purposes only; the audit prompts teach verification and do not constitute financial, investment, or career advice. Prompt outputs vary by model and version. The author and publisher disclaim any liability for actions taken based on this information.