Key Takeaway
- 🎛️ The knob: test-time compute is the computing effort an AI model spends while answering — thinking harder at inference instead of only learning harder at training; it turned “how smart is the model” into “how long should it think on this problem.”
- 🔁 How it works: multi-pass reasoning and self-refinement, best-of-N sampling scored by a verifier (one research report measured up to 4× problem-solving gains over single-pass answers), process supervision that grades each reasoning step, and search over reasoning paths (beam and Monte Carlo tree search).
- 📈 The second scaling law: the field now scales two axes — training-side compute and test-time compute; the first built the models, the second decides how hard they think per question, and the o1-era showed reasoning accuracy rising with thinking time.
- 💵 The cost dial you actually feel: thinking longer costs tokens — the dial trades speed, quality and price per answer, which is why the pricing math in our inference-cost formula is the practical companion piece.
- ⚠️ The limits, stated: search pays most on hard problems and little on easy ones; the returns vary by task; and the “how long should AI think” question has no universal answer — it is a budget, and this piece shows how to set it.
Test-time compute is the quiet change that reshaped what AI models can do: instead of answering instantly from a fixed set of learned weights, a model can now spend extra computation while answering — drafting candidate answers, checking its own steps, exploring alternate paths — and trade time for accuracy on demand. The reasoning-model era (the o1-class systems onward) made the knob explicit, and every serious AI product now prices thinking time as a dial. This piece defines the term, walks the four techniques under it, explains the second scaling law it created, and ends where an operator needs it: how much thinking time each class of task deserves.
Table of Contents
Why the term suddenly matters to non-researchers: because it moved from papers to pricing pages. When a model offers “high reasoning effort” tiers, the meter behind the tier is test-time compute — and the difference between burning twenty and two thousand thinking tokens on a document task is the difference between a reasonable bill and a surprising one (the per-token arithmetic lives in our inference-cost formula).
What test-time compute is — the definition and the history
Definition: test-time compute is the computational effort a model expends during inference — when the trained model generates output for a new input — as opposed to training-time compute, which was spent building the model. In plain words: the model is fixed; the question is how much work it does per answer. The lineage is old and respected: System-1/System-2 thinking theory describes exactly this split (fast instinctive answers vs slow deliberate ones), and the research survey literature traces modern test-time compute to that division — the survey work on deliberate inference frames the whole field as making models “think out loud”: generating intermediate steps, exploring multiple approaches, and evaluating candidates before committing.
The moment it became product: the o1-class reasoning models packaged it — visible chain-of-thought, longer “thinking” phases, and accuracy curves that rose with thinking time on hard tasks. Since then every frontier family shipped a reasoning tier, and “reasoning effort” settings became a normal control. The field’s own term for the era shift — “the era of test-time compute” — stuck because the change was structural: compute became a per-question budget rather than a fixed model property.
How it works: the four techniques
1 — Multi-pass reasoning and self-refinement. Instead of one forward pass, the model drafts, critiques and re-drafts its own work: generate several candidate answers or intermediate solution chains, refine the strongest, iterate. The refinement techniques have names — guided self-revision (the model critiques and corrects its own drafts) and process supervision (a reward model grades each intermediate step, not just the final answer), the latter keeping the reasoning chain on track step by step.
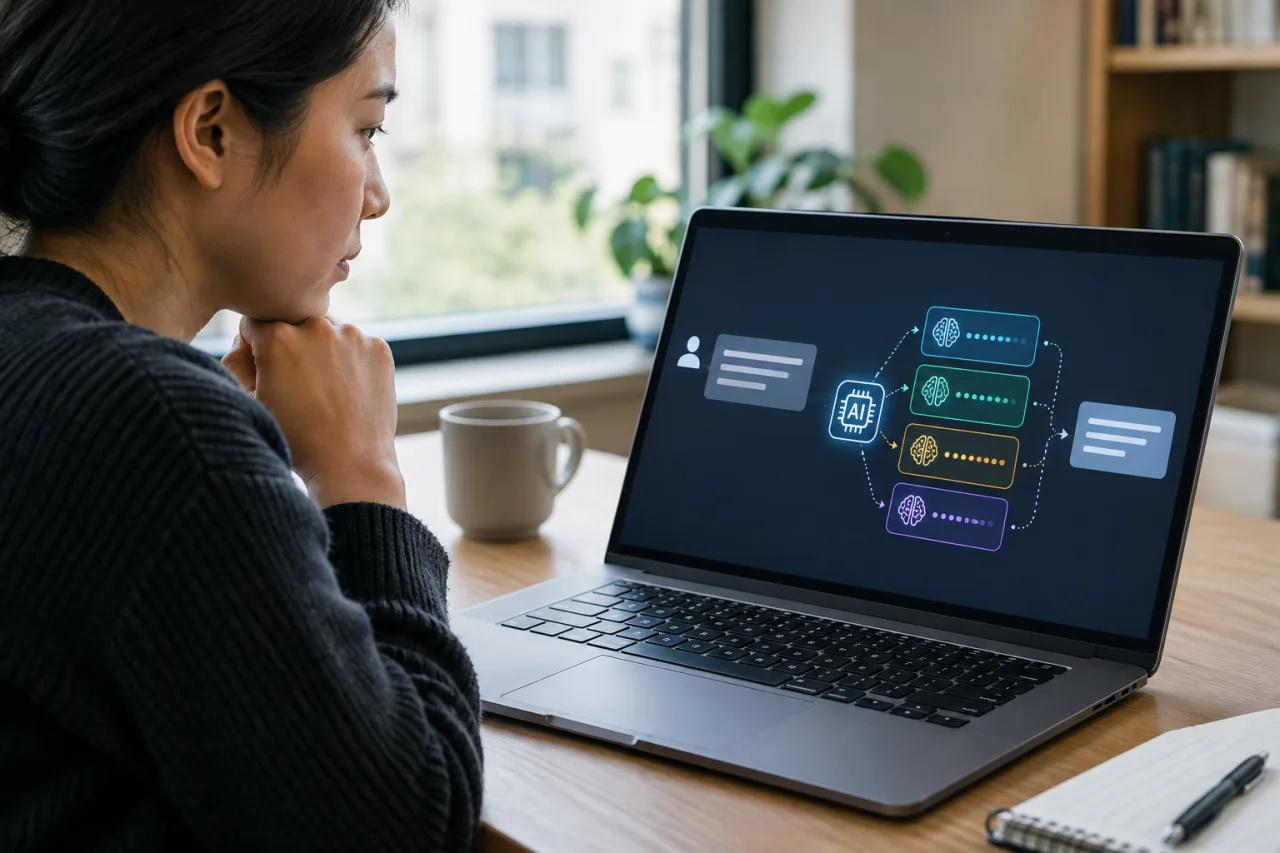
2 — Best-of-N with verification. Generate N candidate answers, score them with a verifier, ship the best. It is the simplest and most measured form: research reports on it note gains up to about 4× in problem-solving efficiency versus naive single-pass generation — the verifier, not just the generator, is part of the system. This is also the technique whose cost curve is easiest to model: N times the tokens, once, with a selection step.
3 — Search over reasoning paths. Beam search, lookahead, and Monte Carlo tree search explore branching chains of reasoning — trying paths in parallel, pruning the dead ends, escalating on the promising ones. Tree search helps most on genuinely hard problems (where multiple approaches differ) and is often overkill on easy queries — the technique’s own papers say exactly that, which is why the practical rule is search on demand, not always-on.
4 — Algorithms that teach themselves to think longer. The STaR family (Self-Taught Reasoner) iteratively refines reasoning during inference: generate multiple solutions, evaluate, feed the improvements back into the reasoning style; extended variants combine self-generated reasoning with bootstrapped training. These blur the training/inference line deliberately — the technique list evolves, but the shared idea holds: making better use of the compute spent per question.
The second scaling law: thinking longer vs training harder
The first scaling law of the 2020s: accuracy rises as training compute, data and parameters grow — the law that built the modern models. The second: on many tasks, accuracy also rises as inference-time compute grows — a knob that did not exist for classic models. The two laws are not rivals; they compose: training-side scaling builds capability, test-time scaling exercises it. The reason the second law matters commercially is that it is per-question: a user or an API caller sets the thinking budget per task, which makes intelligence partly a purchasing decision rather than purely a model-selection decision.
What the curves actually show: reasoning accuracy rises with thinking budget on math, code and structured problems — with diminishing returns that arrive at different points per task (the survey literature is explicit that the returns are task-dependent and that some tasks saturate quickly). The honest phrasing: more thinking time helps most where the problem has verifiable intermediate structure — math steps, code correctness, logic chains — and helps least where quality is taste-based or verifiers are weak.
The cost dial: speed vs quality vs price
Why this is an operator’s question: reasoning tokens are billed like every other token. A support-chat workload that turns on maximum reasoning pays for chain-of-thought on every trivial question; a legal-analysis pipeline that runs minimal reasoning pays in error-rework instead. The dial converts the speed-vs-quality-vs-cost triangle from theory into a settings row — and the 2026 pricing pages made it explicit (reasoning-effort tiers). The budget arithmetic: reasoning tokens multiply the effective cost per answer by the thinking-to-answer token ratio — sometimes five to twenty times on hard tasks — which is why the inference-cost formula now treats “thinking multiplier” as a first-class variable.
The practical settings table: drafting and chat stay low-effort (the verifier adds little on taste tasks); code and math escalate (verifiable structure rewards search and best-of-N); analysis and review run medium-with-verification; the high tier is reserved for problems with checkable answers and real cost of error. Teams that set the dial per task class — rather than globally — get the gains without the bill shock; teams that set it globally discover that the law of diminishing returns shows up as an invoice.
Where it helps — and where it wastes money
Helps most: competition math and logic (verifiable chains, the original showcase), code generation and debugging (tests verify; search pays), planning multi-step tasks where intermediate errors cascade (process supervision’s natural home), and high-stakes document analysis where a verifier can be built. Wastes money: simple classification and extraction (the single pass already suffices), taste-generated creative drafting (no verifier beats preference), latency-sensitive chat (users abandon slow answers regardless of quality), and any task whose verifier is weaker than the generator — ranking candidates with a bad judge just adds cost and noise.
The honest failure modes: overconfident verification (the verifier’s own errors compound), reasoning that becomes confabulation with extra steps (longer chains can rationalize a wrong premise more fluently), and latency cliffs — a model that “thinks” too long fails the interaction even when the answer is better. The security literature adds a wrinkle: longer visible reasoning exposes the model’s chain to prompt-injection and leakage risks — an operator governs what the thinking shows, not just what it costs (our prompt-injection defense playbook carries the guardrails).
The security and governance wrinkle
Test-time compute changed governance in two ways. First, the reasoning trace is data: chains of thought can leak sensitive context from the prompt, reveal internal controls, or carry injected instructions deeper into the system — enterprises that log reasoning traces inherit a retention and exposure question (the logging law is simple: traces are records; redact and retain accordingly). Second, effort settings are now an attack-relevant surface — an adversary who can raise the reasoning budget on THEIR queries pays your bill, and one who can distort the verifier biases the selection. The operator’s checklist: cap effort by endpoint, verify-by-design (tests and validators outside the model), and treat reasoning traces as regulated artifacts exactly like any application log.
WorldNgayon Insight: thinking time is a budget, not a virtue
The discourse mistake this term invites is moral framing — “the AI that thinks longer is better” — which misprices the actual mechanism. Test-time compute is a budget with returns that vary by task structure: it converts verifiable problems into more-accurate answers at a known cost, and it converts unverifiable ones into slower, costlier guesses. The teams extracting real value run the same discipline this site applies to every infrastructure spend: measure the return per token class, escalate only where verification can judge the output, and treat “more reasoning” as a purchasing decision — not a philosophy. The knob made intelligence partly rentable; the discipline that uses it well is knowing when not to rent.
What this means for work, money and the Philippines
Budgets: set reasoning effort per task class, not platform-wide — the settings row saves multiples on chat and spends them where verification pays; the cost formula is the worksheet. Careers: the skill market added a job — inference-effort tuning (which tier, which verifier, which tasks) is now a real competency in AI teams, interviewable in one scenario: “here are five workloads; set the dials and justify the bill.” For Filipino professionals and OFWs: the practical read is direct — the reasoning tiers you see in AI products are this knob, and the discipline of matching effort to task is the difference between tools that pay for themselves and subscriptions that quietly bill you for overthinking spreadsheets. Use the high-effort settings for contracts, code and analysis; keep chat and drafting on the fast lane; and check the bill monthly — the dial’s whole point is that thinking time is now a line item you control.
Verdict: set the dial by the task
Test-time compute, defined once: the per-question thinking budget — four techniques (refinement, best-of-N with verification, search, self-taught reasoning), one second scaling law, one cost curve, and one operating rule: effort follows verifiability. The field’s error would be treating it as free intelligence; the operator’s win is treating it as rentable compute with a returns curve. Set the dial by the task — that is the whole discipline.
Sources on the record: the Hugging Face test-time compute explainer · the RAND test-time analysis.
Financial Disclaimer
This article is editorial analysis of publicly reported engineering, market and policy information, not investment or financial advice, and no outcome is promised. Prices, projections and program plans change; verify with the named sources. Technology markets carry substantial risk.
The dial also has a ceiling worth naming: latency. An answer that thinks for two minutes fails a live conversation even when it is better – interaction quality is a budget line like any other. The mature deployments therefore cap thinking time per endpoint, not just per task: chat and extraction endpoints get hard ceilings, analysis endpoints get budgets with verifiers, and the ceilings are monitored like any other SLA. Thinking time, in the end, is governed infrastructure – the same discipline that prices tokens governs seconds.
- huggingface.co/blog/Kseniase/testtimecompute — the Hugging Face test-time compute explainer
- rand.org/pubs/commentary/2025/03/when-ai-takes-time-to-think-implicat… — the RAND test-time analysis
External sources linked in this article, in order of first mention. Spotted an error or a broken link? Tell us.
Cite this pagePublished Oct 28, 2026
Agron, E. (2026, October 28). Test-Time Compute: the Scaling Knob That Changed How AI Answers. WorldNgayon. https://worldngayon.com/test-time-compute/
Agron, Edmon. “Test-Time Compute: the Scaling Knob That Changed How AI Answers.” WorldNgayon, 28 Oct. 2026, worldngayon.com/test-time-compute/.
Agron, Edmon. “Test-Time Compute: the Scaling Knob That Changed How AI Answers.” WorldNgayon, October 28, 2026. https://worldngayon.com/test-time-compute/.
Agron, E. (2026) ‘Test-Time Compute: the Scaling Knob That Changed How AI Answers’, WorldNgayon, 28 October. Available at: https://worldngayon.com/test-time-compute/.
E. Agron, “Test-Time Compute: the Scaling Knob That Changed How AI Answers,” WorldNgayon, Oct. 28, 2026. [Online]. Available: https://worldngayon.com/test-time-compute/
@online{agron2026testtime,
  author       = {Agron, Edmon},
  title        = {{Test-Time Compute: the Scaling Knob That Changed How AI Answers}},
  year         = {2026},
  date         = {2026-10-28},
  organization = {WorldNgayon},
  url          = {https://worldngayon.com/test-time-compute/},
  urldate      = {}
}TY - ELEC AU - Agron, Edmon TI - Test-Time Compute: the Scaling Knob That Changed How AI Answers T2 - WorldNgayon PY - 2026 DA - 2026/10/28/ UR - https://worldngayon.com/test-time-compute/ Y2 - ER -
Cite the version you read; the page may be updated. Zotero and Mendeley can also import this page directly.