Table of Contents
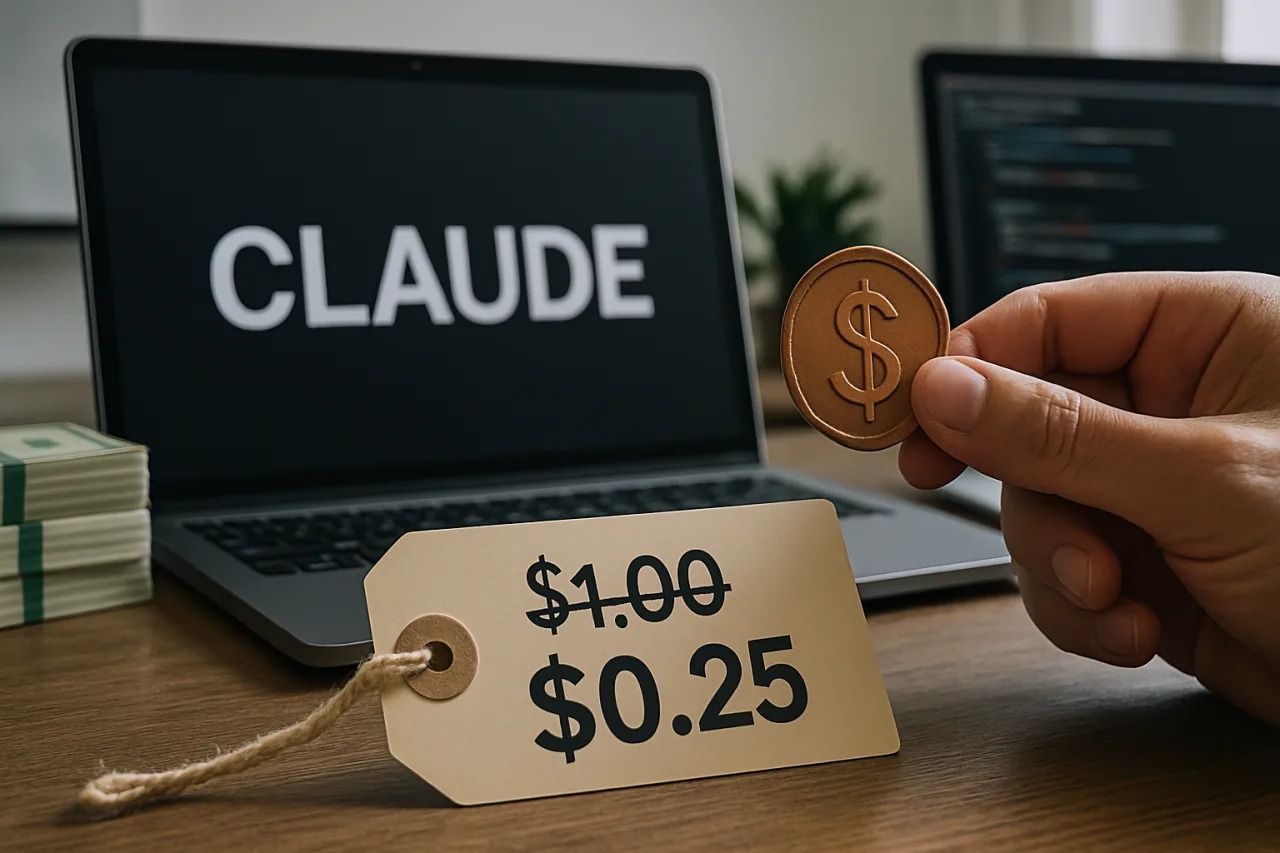
Claude Fable 5.1 is Anthropic’s answer to a question every AI subscriber quietly asks: am I paying frontier prices for last year’s workflow? The model — released September 1 alongside its restricted Mythos 5.1 twin — keeps Fable 5’s input/output pricing ($10/$50 per million tokens) while cutting cache reads to $0.25, a 75% reduction that Anthropic’s own Claude Code team translates into “up to 38% cheaper for a typical session.” More consequentially for the working professional: it is explicitly tuned for long-running agentic work — the multi-hour coding sessions, document pipelines, and research chains where earlier models “became hard to follow the longer they worked,” in the words of Boris Cherny, the creator of Claude Code. This guide covers what Claude Fable 5.1 actually changes, who should upgrade their workflows around it, and where the honest limits sit.
Key Takeaway
- 💰 The pricing shift: Same $10/$50 rates as Fable 5, but cache reads drop from $1.00 to $0.25 per million tokens — the biggest effective cost cut Anthropic has shipped.
- 🛠️ The capability: Stronger long-horizon agentic coding and multi-step work; 73.4% on CursorBench 3.2 per Anthropic’s launch data, with stronger self-verification.
- 🧪 The twin: Mythos 5.1 is the same model with lighter safeguards — invitation-only for vetted cybersecurity and life-sciences researchers via Project Glasswing.
- 👤 Who should care: Claude Code users and long-session workers see the gains first; casual chat users will mostly notice speed and price.
Every AI model release is a pricing announcement wearing a capability costume. Claude Fable 5.1 inverts the pattern: it is a capability announcement wearing a pricing cut — and the pricing cut is aimed at the exact workload (long agentic sessions) where costs previously spiraled. Reading Claude Fable 5.1 as “another model update” misses the strategic point; reading it as Anthropic repricing the agent-workload market explains why the launch quotes came from the Claude Code team rather than the research team.
What Claude Fable 5.1 Actually Changes
Three substantive deltas from Fable 5, per the launch documentation and the VentureBeat launch analysis. Economics: cache reads at $0.25/Mtok (down from $1.00) — a structural cut for anyone running repeated agentic sessions, where the same context gets re-read dozens of times; the “38% cheaper Claude Code session” claim is the vendor’s arithmetic and checks out directionally against the price list. Agentic durability: the model is tuned to remain coherent over long multi-step tasks — the failure mode where prior models drifted, contradicted themselves, or lost the thread over hours. Self-verification: stronger checking of its own work, which matters for coding agents whose value proposition is “finished, correct output” rather than plausible drafts. Safeguards: cyber-protections that reportedly produce ~60% fewer false interventions per Claude Code session than Fable 5’s — fewer interruptions for legitimate work, which is itself an agentic-quality improvement. [VD — vendor-reported figures]
The Mythos Split: One Model, Two Guardrails
The most consequential design decision in the launch is the bifurcation. Claude Fable 5.1 is what everyone gets: the full model with standard safeguards. Claude Mythos 5.1 is the same underlying model with lighter safeguards on cyber and bio capabilities — restricted to vetted researchers through Project Glasswing, the invitation-only access program detailed in Anthropic’s official announcement. The split is Anthropic’s answer to the dual-use dilemma: rather than hobbling the model for everyone to protect against the few, they ship the full capability but gate the dangerous configuration behind verification. The Zvi Mowshowitz analysis of the launch frames the trade honestly: this is a real safety-architecture experiment running at frontier scale, and its success or failure will inform whether capability-gated access becomes the industry’s standard pattern. For the reader deciding whether to care: Fable 5.1 is what you’ll actually touch; Mythos is the policy experiment running in parallel.
The Agentic Workload: Where the 5.1 Gains Land
Who actually feels this release? Segment by workload. Claude Code users and API developers: the primary beneficiaries — the cache-read cut compounds over long sessions, and the improved self-verification reduces the review burden that makes agentic coding expensive in human time. Long-document professionals: the 1M-token context window plus improved coherence means contract analysis, literature reviews, and multi-file refactors that previously required careful chunking now run as single sessions. Casual chat users: you’ll notice faster responses and lower plan-tier friction, but the headline capabilities — long-horizon agency, tool orchestration — are not the chat use case. Enterprise buyers: the Fable 5.1 release coincides with reduced Enterprise/API pricing tiers and the agentic-safety improvements that procurement teams increasingly audit. The segment that should wait: anyone whose workflow is short, single-turn Q&A — the gains are real but marginal there, and last generation’s models remain excellent at it. The upgrade case strengthens with session length; that is the release’s design signature, and it is why the Claude Code community’s early reports dominate the launch conversation.
The Competitive Frame: Pricing Against a Closing Gap
The launch reads differently against this month’s backdrop of an accelerating market. OpenAI’s own price reductions and the open-weight agentic releases we covered — from Atria Dawn’s MIT-licensed 744B agent to the Kimi generation — have repriced what frontier-adjacent capability costs. Anthropic’s answer is layered: keep the headline price, slash the repeated-workload cost (cache reads are exactly where agentic workloads bleed), and pair it with the “most capable model on CursorBench” claim to justify the premium over open alternatives. The competitive logic is coherent in a market we track weekly — from the industry’s pacing debate to the open-weight releases reshaping prices: open models are free but demand infrastructure and expertise; Fable 5.1 at effective 38%-off for agentic work is priced to sit between “free but hard” and “easy but expensive.” Whether that position holds depends on the open ecosystem’s next moves — and on independent benchmark replication, which is where every vendor launch claim ultimately meets its exam. The honest read: the pricing cut is real and verified against the published price list; the capability margins are vendor-reported and should be treated as strong claims pending independent replication. [UR — independent replication pending]
A Practical Playbook for Switching
For professionals already in the Claude ecosystem, the migration is nearly zero-effort — the model selector exposes Fable 5.1 alongside its predecessors, and the API identifier (`claude-fable-5-1`) drops into existing integrations without parameter changes. The Claude Fable 5.1 playbook by user type: Claude Code subscribers should simply switch and re-run one real project — the cache savings and the coherence-over-length improvements are the two things worth verifying against your own workload rather than the launch blog’s. API builders should re-run their eval suites; the pricing change alone may shift which model is optimal for your batch jobs. Chat-tier users: nothing to do — the model arrives in the interface. The one workflow worth auditing is caching strategy: codebases and document pipelines that were structured to minimize cache re-reads under the old pricing may now be optimally structured differently — the 75% cache cut changes the economics of “keep the context warm.” That is the rare kind of release detail that translates directly into invoice differences, and it is the change most likely to outlast the launch-cycle noise.
The workflow redesign question deserves its own concrete examples, because “audit your caching” is abstract until it isn’t. A contract-review pipeline that previously split a 900-page corpus into per-session chunks — because re-sending the reference set every session was ruinous — can now keep the corpus cached and pay a quarter of the old re-read price; the chunking logic that was an economic necessity becomes an optional architecture choice. A coding agent that restarted sessions to avoid context bleed can now run longer under a model explicitly tuned for that horizon, converting integration-checkpoint overhead into continuous work. And a research desk that kept a “summary layer” — compressed notes standing in for full documents, purely to dodge re-reading costs — can reconsider whether the compression loss is still worth it at the new prices. None of these examples requires new tooling; they require revisiting decisions that were made under old prices. The teams that re-run that arithmetic first get a structural cost advantage over teams that treat 5.1 as a drop-in replacement, because the pricing change is not uniform — it specifically rewards whoever restructures for it first.
The failure modes deserve equal billing. Long-context confidence is not correctness: a model that stays coherent for three hours can stay confidently wrong for three hours, and the improved self-verification reduces but does not eliminate the need for human checkpoints on consequential outputs. The agentic improvements also widen the blast radius of a bad instruction — the boundary questions our agent autonomy limits analysis raises apply directly — an agent that completes more of its task chain without checking in also completes more of a mistaken task without asking. The professionals best positioned for this release are those whose workflows already include verification gates: review points where a human confirms direction before the agent continues. The release raises the ceiling on what a supervised agent can do; it raises the cost of supervising carelessly by exactly the same amount. That pairing — capability up, stakes up — is the honest summary of every frontier release this year, and Fable 5.1 is no exception.
The timing question completes the picture. Anthropic shipped Claude Fable 5.1 on September 1 — two weeks into a month that also brought OpenAI’s Astra-adjacent releases, the open-weight agentic wave from Shanghai, and the Dreamforce demonstrations of enterprise agents running inside other companies’ assistants. In that context, a 75% cache-read cut is not a product detail; it is a competitive position in the month’s central argument about what AI work should cost. The professional’s move is the same one this publication has applied to every repricing event this quarter: verify the claim against your own usage, re-architect where the math changed, and hold the rest lightly — because the next repricing is already scheduled, whoever ships it.
Frequently Asked Questions About Claude Fable 5.1
What is Claude Fable 5.1?
Anthropic’s September 2026 frontier model for coding, knowledge work, and long-running agentic tasks — an upgrade over Fable 5 with stronger long-session coherence and self-verification, at unchanged base pricing ($10/$50 per million tokens) with cache reads cut 75% to $0.25. It is available across Claude apps, the API, and the major cloud platforms.
How much cheaper is Claude Fable 5.1 than Fable 5?
Base token prices are unchanged; the cut is on cache reads — $1.00 to $0.25 per million tokens. Anthropic says that makes a typical Claude Code session up to 38% cheaper. For long agentic sessions where the same context is re-read repeatedly, the savings compound further; for short single-turn chats, the difference is small.
What is the difference between Fable 5.1 and Mythos 5.1?
Same underlying model, different safeguard configurations. Fable 5.1 is generally available with standard protections. Mythos 5.1 exposes lighter safeguards for cyber and bio capabilities and is restricted to vetted researchers through Anthropic’s Project Glasswing invitation program. Regular users interact only with Fable.
Is Claude Fable 5.1 good for coding?
It is Anthropic’s most capable coding model per their launch benchmarks — 73.4% on CursorBench 3.2 at max effort, with self-verification improvements aimed at long-running agentic coding sessions. Early Claude Code community reports emphasize sustained coherence on multi-hour tasks. Treat the vendor benchmarks as strong claims pending your own workload testing.
Do I need to change anything to use Claude Fable 5.1?
Claude app users see it in the model selector automatically, alongside the coworker-style workflows our Claude coworker setup guide documents. API users swap the model identifier to `claude-fable-5-1`. Power users should audit their caching strategy — the 75% cache-read reduction changes which prompt architectures are cheapest, and re-tuning that is where the release pays for itself.
How does it compare to open-weight models like Atria Dawn?
Different value propositions: open models are free to self-host but demand infrastructure and expertise, while Fable 5.1 offers frontier capability with zero infrastructure at metered cost — now with a much cheaper repeated-session profile. The honest comparison runs through your own workload: benchmark both on real tasks before committing either way, as our open-model coverage recommends.
This article is for general information only and does not constitute investment or purchasing advice. Benchmarks and pricing are from vendor materials and press coverage as of September 2026; verify current pricing and capabilities with the vendor before decisions.
Financial Disclaimer
This article is published for general information and technology education. It is not investment or purchasing advice. Pricing, benchmarks, and feature claims are from vendor materials and press coverage as of September 2026 and change frequently; verify current terms with the vendor before making subscription or API decisions.