Table of Contents
Key Takeaway
- 🧭 The term is settled: context engineering is the deliberate curation of everything an AI sees before it answers — instructions, knowledge, tools and memory in one window.
- 🗣 It came from the top: Shopify CEO Tobi Lütke coined the phrase in June 2025 and Andrej Karpathy gave it the viral +1 — because prompts alone stopped explaining why agents failed.
- 📏 Attention is a budget: Anthropic’s engineering blog frames the goal as the smallest set of high-signal tokens that carries the task — not the biggest pile of text.
- 🔁 Long tasks have only three proven tactics: compacting the conversation, structured note-taking, and delegating to sub-agents — the same trio Anthropic ships inside Claude Code.
- 🧪 You can practice in 20 minutes: five slots — task, facts, format, examples, guardrails — turn any sloppy chat into an engineered context, no code required.
Context engineering is the discipline of deciding what an AI model sees — and in what shape — before it generates anything. A prompt is one sentence in that context; a system message, a retrieved document, a tool result and a memory file are four more. In 2026 the practitioners who use AI daily stopped arguing about prompts and started designing the whole window, because the window — not the sentence — decides whether the output is usable. This piece defines the term from its primary sources, maps the layers, shows the three tactics that survive long tasks, and ends with a 20-minute practice pass anyone can run today.
How the term arrived: a reply that named the discipline
The lineage is unusually clean for a buzzword. In June 2025, Shopify CEO Tobi Lütke wrote that he preferred “context engineering” over “prompt engineering,” describing it as the composable stack of instructions, retrieved facts, tool outputs, edits and state. Andrej Karpathy — the former Tesla AI director who helped define prompt engineering’s golden era — replied with “+1 for context engineering over prompt engineering,” laying out the fuller job: dispatch calls to the right models, handle generation-verification flows, manage guardrails, security, evals and parallelism. The Karpathy reply and the Anthropic engineering post that followed in September 2025 are the two citations to hold onto; everything else in this field descends from them. For the sibling angle — how the umbrella differs sentence-by-sentence from prompt craft — our context engineering vs prompt engineering comparison walks the five differences.
By late 2025 the academic layer caught up: a survey of over 1,400 papers (assembled by the Sourcegraph engineering team in their 2026 guide) formally defines context engineering as covering context retrieval and generation, context processing and context management. That is the moment a term stops being a hot take and becomes a discipline — when the literature adopts it.
Why prompt engineering lost the umbrella
Prompt engineering optimizes one string. Context engineering designs the whole field of view. The practical failure it fixes is the classic one: a model answers correctly in isolation, then fails inside a real workflow — because the real workflow buried the instruction under stale search results, a tool output that lied, or a chat history three hundred turns long. The prompt was never the problem; the surrounding window was.
Anthropic’s agents post gives the field its sharpest metaphor: attention is a budget. Every token you add spends attention the model would otherwise spend on your instruction, so the goal is the smallest set of high-signal tokens that carries the task. Retrieval, not stuffing, is the operating principle — the difference between a curated briefing and a filing-cabinet avalanche.
The four layers of a context-engineered window
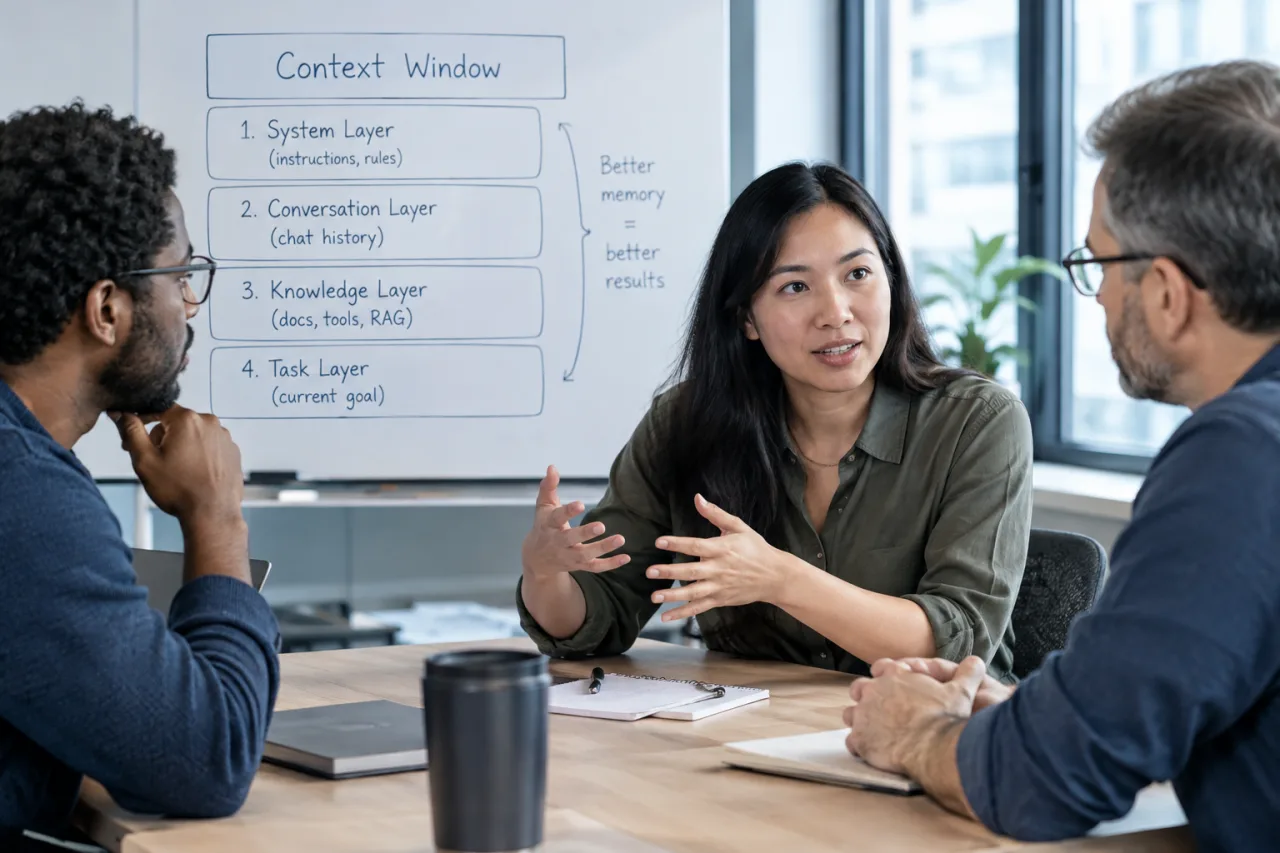
Every production window decomposes into the same four layers:
- Instructions: the system message and task statement — role, rules, output format, boundaries.
- Knowledge: retrieved facts the model cannot know alone. RAG (retrieval-augmented generation) is the most famous technique here, and one layer among many — as the 2026 upsolve comparison puts it, RAG answers “how do I fetch relevant knowledge,” while context engineering answers “what should the model see at all, and in what form.”
- Tools: schemas and permissions that let the model act — search, calculators, databases, code runners.
- Memory and state: notes, summaries and files that persist across turns, so the conversation does not pay rent for 300 stale exchanges.
The layers compose: a well-engineered window changes layer one weekly, refreshes layer two on every document, audits layer three quarterly, and grows layer four slowly. Teams fail by treating all four as one undifferentiated blob called “the prompt.”
The three tactics that survive long tasks
Anthropic’s post (summarized alongside by The Decoder) names exactly three tactics for work that outgrows one window:
- Compacting: summarize the conversation near the window’s limit and restart with the compressed summary — the agent keeps its goal and loses its clutter.
- Structured note-taking: keep critical facts (plans, decisions, TODOs) in a persistent file outside the window, re-read on demand — Claude Code plays Pokémon across multi-hour sessions this way.
- Sub-agents: hand isolated subtasks to child agents with their own clean windows; the main agent coordinates and reads back only the distilled results.
All three share one principle: the window stays curated while information lives outside it. That principle is why this discipline exists at all — windows are finite and attention is a budget, so the engineering is in deciding what stays.
A 20-minute context engineering pass you can run today
The practice is not only for platform builders. Any daily AI user can engineer a context in five slots:
- Task: one sentence stating the deliverable and the audience. (“Draft a 150-word client update in plain English, neutral tone.”)
- Facts: only the facts the task cannot proceed without — numbers, dates, names. Delete the rest.
- Format: the exact output skeleton — headings, fields, lengths. Models follow shapes better than adjectives.
- Examples: one good example, one bad example. Two examples triple the instruction’s precision.
- Guardrails: the two ways the answer must not go wrong — banned topics, banned phrasings, the escalation path.
Save the slots as a template file and reuse: that file is your first context engineering asset, and it beats every prompt library because it composes — the slots accept new facts without rewriting the instructions.
The builder’s view: what context engineering looks like in production
Open a serious 2026 AI codebase and the discipline is visible as files. Coding agents ship rules files — a Cursor rules file, a Claude memory file — which are exactly layer one and layer four materialized as text the whole team can review in a pull request. The Model Context Protocol (MCP), the open standard for connecting tools that we catalogued across our MCP servers list, standardized layer three: one schema format means any tool (search, database, design canvas, payment rail) can drop into any agent’s window with predictable permissions. And the agent frameworks grew state management as a first-class object — LangGraph-style checkpoints persist task state so a crash does not vaporize the budget.
The tell of a mature builder is what they delete. Early prototypes stuff the window with everything “just in case”; production teams prune, because every stale tool schema, every duplicate instruction and every irrelevant search result spends attention that the core task needs. Karpathy’s original reply listed the real job as a supply-chain discipline: the right dispatches, generation-verification flows, guardrails, evals, parallelism, prefetching — the wording of a systems engineer, which is what context engineering became.
The economics: tokens, caches and the cost of a bloated window
Context engineering has a unit cost, and 2026 pricing made it visible on every invoice (the tool-layer plumbing behind it, from search to databases, is what our MCP servers guide catalogues). Inference bills scale with tokens read and written, so a window stuffed with 50 documents costs 50 documents’ worth of input tokens on every single call — the fat window is a subscription you pay per request. The practical countermove became prompt caching, which providers price at a fraction per repeated read: put the stable layers (instructions, tool schemas, reference documents) first and the changing layer last, and the cached prefix bills at reduced rates on every subsequent call. Structure, in other words, is literally savings.
Latency follows the same curve: prefill time grows with the window, so bloated contexts answer slower before the model has “thought.” Teams that engineered their windows report the boring truth — the same model, same task, faster and cheaper, once half the noise was removed. The budget discipline from Anthropic’s post is thus also a finance discipline: smallest set of high-signal tokens, billed once, cached well.
The team playbook: shared windows without chaos
When five people share one agent, the context engineering question becomes governance — a theme regulators are already circling, as Singapore’s agentic AI framework shows for the institutional layer. The working team playbook is unglamorous and effective: keep the instructions layer in a reviewed file (versioned like code), assign one owner per tool schema in the tools layer, log what the memory layer persists, and run a weekly window-audit — open the actual context a real request sees and delete what nobody defends. Treat the window like a shared kitchen: labeled shelves, no hoarding, a closing checklist.
Security rides the same rails. Tool outputs are the classic injection point — a poisoned document becomes context, and poisoned context steers the model. The vibe-coding security checklist in our build-and-ship security guide treats agent context as an untrusted input, and the Singapore agentic-AI framework institutionalizes the same discipline at national scale. Curate sources, whitelist tools, and never let a retrieved page rewrite your instructions layer.
Where RAG fits in context engineering
RAG is the retrieval layer — one of the four — and the full build lives in our private RAG guide — and the 2026 consensus keeps long context windows and retrieval as complements, not rivals: long windows let you fetch the right chunk and afford the right surrounding text. For the build-side walkthrough, our private RAG guide shows the no-cloud version of layer two end to end. The distinction to hold: a RAG system is infrastructure; context engineering is the design discipline that decides what the infrastructure feeds the window.
The failure modes that give the game away
Three repeat offenders: context rot — long conversations degrade before the window is technically full; overstuffing — dumping whole documents because retrieval costs effort, which spends the attention budget on noise; and instruction drift — the original task sentence gets diluted by later tool outputs until the model serves the document instead of the user. Each has the same cure: curate. The window is a budget, and context engineering is the budgeting office.
Frequently Asked Questions
What is context engineering in simple terms?
It is choosing everything an AI sees before it answers — instructions, facts, tools and memory — so the model spends its attention on the task that matters, not on noise. A prompt is one part of that picture.
Who coined the term context engineering?
Shopify CEO Tobi Lütke wrote it in June 2025 and Andrej Karpathy’s reply made it stick; Anthropic’s September 2025 engineering post gave it its working definition for agents.
Is context engineering replacing prompt engineering?
It absorbs it. Prompt craft still matters — as the instructions layer — but the failures users hit today are window-design failures: stale retrieval, bloated history, missing tools. The discipline covers those; a prompt alone cannot.
Where does RAG fit in context engineering?
RAG is the retrieval layer: it answers “how do I fetch relevant knowledge.” Context engineering answers the wider question — what the model should see at all and in what form — including tools, memory and formatting.
What is the difference between context engineering and RAG?
RAG is one retrieval technique inside the wider discipline: it fetches knowledge, while context engineering decides what the whole window holds — instructions, tools, memory and formatting included.
Does context engineering save money?
Yes. Tokens are billed on read and written volume, so a smaller, well-structured window costs less per call — and stable prefixes that support caching bill at a fraction on repeat. Structure is savings.
Can a non-programmer practice context engineering?
Yes — the five-slot pass (task, facts, format, examples, guardrails) is a text-editing exercise. Every serious AI product and every careful user composes these slots daily.
Sources: Karpathy reply (x.com, June 2025); Anthropic engineering blog post and X announcement (September 2025); The Decoder summary; Sourcegraph 2026 guide citing the 1,400-paper survey; upsolve.ai 2026 RAG comparison; taskade.com 2026 definition. This is general information, not a vendor endorsement.
Financial Disclaimer
Financial Disclaimer: This article is general information and education, not investment advice. Token pricing and provider terms change without notice; verify current rates with your provider. The authors hold no positions in any provider named.
Financial Disclaimer
Financial Disclaimer: This article is general information and education, not investment advice. Token pricing and provider terms change without notice; verify current rates with your provider. The authors hold no positions in any provider named.
Cite this pagePublished Nov 14, 2026
Agron, E. (2026, November 14). Context Engineering: the Skill That Decides What Your AI Remembers. WorldNgayon. https://worldngayon.com/context-engineering-guide/
Agron, Edmon. “Context Engineering: the Skill That Decides What Your AI Remembers.” WorldNgayon, 14 Nov. 2026, worldngayon.com/context-engineering-guide/.
Agron, Edmon. “Context Engineering: the Skill That Decides What Your AI Remembers.” WorldNgayon, November 14, 2026. https://worldngayon.com/context-engineering-guide/.
Agron, E. (2026) ‘Context Engineering: the Skill That Decides What Your AI Remembers’, WorldNgayon, 14 November. Available at: https://worldngayon.com/context-engineering-guide/.
E. Agron, “Context Engineering: the Skill That Decides What Your AI Remembers,” WorldNgayon, Nov. 14, 2026. [Online]. Available: https://worldngayon.com/context-engineering-guide/
@online{agron2026contextengineering,
  author       = {Agron, Edmon},
  title        = {{Context Engineering: the Skill That Decides What Your AI Remembers}},
  year         = {2026},
  date         = {2026-11-14},
  organization = {WorldNgayon},
  url          = {https://worldngayon.com/context-engineering-guide/},
  urldate      = {}
}TY - ELEC AU - Agron, Edmon TI - Context Engineering: the Skill That Decides What Your AI Remembers T2 - WorldNgayon PY - 2026 DA - 2026/11/14/ UR - https://worldngayon.com/context-engineering-guide/ Y2 - ER -
Cite the version you read; the page may be updated. Zotero and Mendeley can also import this page directly.