Table of Contents
Key Takeaway
- 🧩 The Jev AI model’s contract: Jev does not try to write the answer. It evaluates a defined state and returns typed choices, scores or probabilities that software can consume.
- ⚡ The real advantage: Constrained outputs can reduce parsing, latency and output-token costs in repetitive decisions such as routing, moderation, scoring and guardrails.
- 🎯 The boundary: Jev is not a chatbot, coding model, calculator or multimodal assistant. TypeSafe documents weaknesses in counting, arithmetic, dates, indirection, long irrelevant context and text generation.
- 🔬 The market signal: Cloudflare, AWS and OpenAI are building related decision-model interfaces. The important shift is the decision layer between brittle rules and open-ended language models.
The Jev AI model is interesting for a reason that has little to do with producing a more impressive chat reply. It changes the contract between an AI model and the software around it. Instead of asking a generative model to write a string, then parsing that string and hoping the result fits the application, a developer defines the possible answers first. Jev returns a typed decision, a probability distribution and, for some question types, a confidence signal.
That sounds narrower than a general-purpose large language model. It is. The narrower interface is the point. The new opportunity is not to replace the model that writes an email or explains a document. It is to give ordinary software a fast judgment layer for the thousands of small decisions that sit inside a modern product: which queue receives a ticket, whether a message asks for a refund, whether a retrieved passage supports a claim, whether an agent should call a tool, or whether a human should review the case.
WorldNgayon’s angle is therefore not “Jev is the next ChatGPT.” It is this: AI systems have been missing a practical middle layer between hand-written rules and open-ended generation. Jev is an early, commercially hosted attempt to fill that layer. Its value will depend less on viral demos than on calibration, evaluation, language coverage, privacy, version control and the quality of the workflow that surrounds it.
What is the Jev AI model actually built to do?
TypeSafe AI released Jev on September 15, 2026, describing it as its first “System One Model.” The name is a reference to the fast, intuitive side of the System 1/System 2 distinction popularized by Daniel Kahneman. In TypeSafe’s definition, a System One model accepts unstructured information but returns structured decisions rather than generated prose.
The official documentation describes three core primitives:
- Choice: Select one option from a defined list, such as billing, technical or account support.
- Score: Place the state on an ordered rubric, such as a customer-frustration scale.
- Noul: Estimate whether a statement is true, returning a value between zero and one.
Several questions can be sent against the same state. The documentation says they are evaluated independently and in parallel. A developer could provide a support message, recent transactions and the refund policy, then ask separate questions about whether the customer requested a refund, whether the evidence suggests a duplicate charge and whether the policy permits a refund.
Seen this way, the Jev AI model is less a conversational destination than a decision component that a product team can place wherever a bounded judgment is needed.
The application—not Jev—then combines those results. Code can require a high enough probability, apply a deterministic business rule and send uncertain cases to a person. That division of labor matters. Jev makes a judgment about the text and data it receives; the surrounding program owns the final action.
That separation is the central Jev AI model idea: model the judgment, but keep the consequence in software that the team can inspect and change.
How the Jev AI model fits into software
A generative model is usually asked to produce an answer in a format the application can understand. JSON mode and structured outputs reduce the risk, but the system still begins with a text-generation interface. The developer must specify a prompt, parse the response, validate fields and decide what to do when the model refuses, omits a field or invents a value.
Jev starts from the opposite direction. The developer defines the answer space before the call. If the question is “Which team should handle this ticket?”, the available answers might be billing, technical and account. Jev cannot return a fourth category or write a paragraph in place of the category. Its output is designed to slot into an ordinary conditional, router or ranking function.
This is more than a formatting preference. It moves part of the safety boundary from prompting into the interface. A type-safe answer cannot solve a bad question, a misleading state or a poorly designed policy, but it removes an entire class of output-shape failures. That is valuable in an agent workflow where one malformed tool call can propagate through several dependent steps.
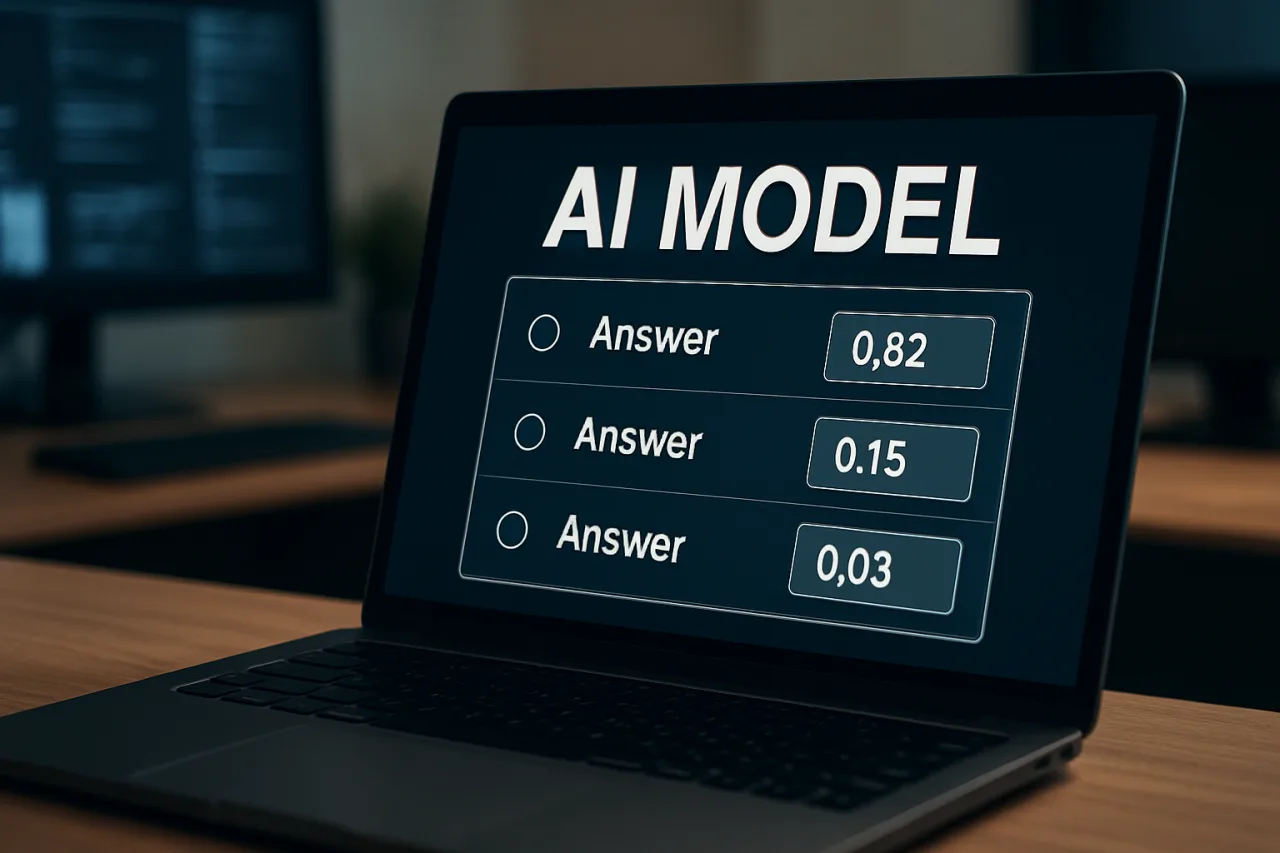
The pattern resembles a fuzzy version of an if statement. Traditional code says: if the rule matches, take branch A. A decision model says: given this state and these criteria, branch A has a 0.87 probability, branch B has 0.10 and branch C has 0.03. The application can set its own threshold, route the uncertain middle to review and preserve the probabilities for later analysis.
That last part is important for operations. A binary answer hides whether the model was nearly certain or barely over the line. A probability does not make the decision true, but it gives the system a way to distinguish automatic handling from escalation.
Why a constrained model can be faster and cheaper
TypeSafe’s current model reference lists Jev 1.13.0 at $0.042 per million input tokens, with output tokens free. The same page lists a 64,000-token request context, a maximum 32,000-token state plus the longest question, and rate limits of 100,000 tokens per second and 80 requests per second. These are the vendor’s current API figures, not a universal cost guarantee; limits can change as the service scales.
The economic logic is straightforward. A generative model produces a sequence of output tokens, even when the application only needs one label. Jev evaluates a bounded set of questions and returns the structured result. TypeSafe also says its parallel sampler and training method—Reinforcement Learning for Calibrated Decisions, or RLCD—are designed around this workload.
For a high-volume product, the Jev AI model becomes interesting only when its narrow output matches a repeated decision. A lower price on an unsuitable task is not efficiency; it is an inexpensive way to create more review work.
TypeSafe’s launch material claims Jev can be 40 to 200 times faster for comparable System One-shaped queries and that its workflow evaluations reached much larger speed and cost differences in selected tests. Those numbers should be treated as vendor benchmarks, not as a promise that every production application will see the same result. Network delay, state preparation, question design, rate limits and the cost of the rest of the workflow still count.
The stronger claim is architectural: if an application runs millions of small decisions, it should not pay a generative-model tax for every one. A cheap decision call can make product features economically possible—real-time filtering, large-scale routing, pre-screening, evaluation and background enrichment—that would be too slow or expensive if every item required a long generated response.
This connects to the cost question we examined in our AI inference cost formula. The price of an AI feature is not just the advertised token rate. It is the number of calls, the size of the state, retries, latency requirements, human review, storage and the cost of errors. Jev attacks one part of that equation: the cost and fragility of small, repeatable decisions.
The Jev AI model does not make those other costs disappear; it gives a team a narrower instrument for controlling them.
The missing layer between rules and LLMs
Software teams have traditionally had two imperfect choices. They could write a deterministic rule, which is fast and auditable but brittle when language varies. Or they could call a general language model, which understands flexible language but is slower, more expensive and difficult to constrain.
Consider a support classifier. A rule can search for words such as “refund,” “charged twice” or “cancel.” It will miss paraphrases and context. A general LLM can understand those variations, but returning a reliable category requires a prompt, structured output handling and validation. A decision model offers a third option: use language understanding to judge a bounded question, then let normal code determine the action.
This is why Jev’s most important competitors are not only other models. They are also regex, rules engines, fine-tuned classifiers, moderation APIs and the expensive generative models that developers currently use as universal classifiers. The decision model wins only when the task is genuinely a judgment problem and the answer space can be described clearly.
The Jev AI model therefore occupies a middle position: more flexible than a keyword rule, more constrained than an LLM and more useful when its uncertainty can be connected to a workflow policy.
It loses when the answer must be invented. Jev cannot draft the customer reply, write a patch, summarize a contract or explain why a decision was made. The model can help a larger system decide what to do next, but a generative model or a human still has to perform the open-ended work.
What independent evaluation says—and what it does not say
An independent preprint from researchers at the University of Bonn and partner institutions provides a useful check on the launch story. Their benchmark evaluated the pinned Jev 1.13.0 model on 37 datasets, covering classification, routing, natural-language inference, reading comprehension, moderation, legal-clause analysis and rubric scoring. The study reports 346,009 requests and publishes its code, harness and raw responses.
In that evaluation, Jev reached between 95% and 99% accuracy on IMDB, SST-2, HellaSwag and ARC. On Belebele, a multilingual benchmark spanning 122 languages, the reported result was 86.7%. Jev beat Qwen3.8-27B on 27 of 37 datasets and Gemma-4-E4B on all 37 in the study’s comparisons. Those are meaningful results, but they are not proof that Jev is the best model for every business classification problem.
The same paper supplies the missing context. Performance fell on low-resource languages, fine-grained or noisy labels and rubric-based quality judgments. The authors also found that Jev’s probabilities were useful for ranking uncertain cases, but binary probabilities were poorly aligned with a fixed 0.5 threshold until thresholds were tuned on training data. A probability score is therefore not a magic “safe to automate” switch.
There is another limit to any benchmark result: Jev’s training data is not public, so benchmark contamination cannot be ruled out. The paper’s result is stronger than a vendor demo because the evaluation is independently run and reproducible, but it remains a preprint and it measures public tasks rather than every production workflow.
The sensible conclusion is narrower and more useful: Jev appears capable on a broad range of zero-shot bounded decisions, and it exposes uncertainty in a way that supports selective prediction. Teams still need to test it on their own labels, languages, false-positive costs and edge cases.
That is the right reading of the Jev AI model evidence: promising as a specialized decision interface, not independently proven as a universal replacement for general AI systems.
Where Jev breaks
TypeSafe’s own “jaggedness” documentation is unusually direct about the current model’s limits. Jev 1.13 is described as fast, calibrated and good at common-sense judgment, but weaker when a task requires multiple layers of indirection or numeric precision. The documentation says it can be literal, and it recommends keeping arithmetic in code.
That warning should change how developers design a workflow. Do not ask Jev to count items that a parser can count exactly. Do not ask it to calculate a date interval, compare timestamps or reconstruct a precise number from score levels. Extract the relevant fields with code or a model, then let code perform the arithmetic.
The documented failure list also includes large states filled with irrelevant detail, adversarial content, contradictory instructions and option-order effects. The current model accepts text, JSON objects and arrays of text. It does not accept images, audio or video directly. The official model page says English is the primary training language and advises testing other languages before relying on them in production.
Most importantly, Jev does not generate text. Forcing it to produce prose through a chain of choices is slow and unreliable. That is not a temporary inconvenience; it is the boundary that creates the model’s usefulness. A builder who needs an explanation should pair Jev with a generative model or write the explanation in code from the decision record.
The Jev AI model is strongest when the team accepts that boundary instead of trying to turn it into a smaller chatbot.
Calibration also needs careful wording. TypeSafe’s documentation explains that calibration is measured across groups of predictions. It does not guarantee that any single answer is correct. A score of 0.90 should drive a tested policy, not blind trust.
Any Jev AI model deployment should treat that distinction as a monitoring requirement, not a footnote.
A practical architecture for builders
The best first experiment is not to replace an existing LLM call. It is to identify a narrow decision that is currently expensive, slow or difficult to audit.
- Keep deterministic work in code. Parse dates, count records, enforce permissions, validate schemas and apply hard business rules without asking an AI model to do arithmetic.
- Prepare a small state. Retrieve and filter the relevant fields before sending them. Do not dump an entire database row or a long conversation into every decision request.
- Split the judgment. Ask one question for urgency, another for category and another for escalation risk. Avoid a single vague question that hides several independent decisions.
- Set thresholds from labeled examples. The right threshold depends on the cost of a false positive and a false negative. Tune it against real application data.
- Keep a human path. Low-confidence and high-impact cases should go to review. A confidence number is a routing signal, not a substitute for professional responsibility.
- Log the version. TypeSafe’s aliases such as
jev-latestcan move when a new release ships. Pin a version when thresholds have been tuned, and record the version returned by the API.
A hybrid agent is the natural design. A generative model can interpret a user’s broad request, retrieve context and produce a response. Jev can cheaply check whether a tool call is grounded, choose among allowed routes, score policy risk or decide whether the next step needs a person. Deterministic code then enforces the final permissions and side effects.
A useful Jev AI model pilot is therefore small enough to measure: one decision, one labeled test set, one threshold policy and one rollback path.
That design also fits the practical AI workflows discussed in our AI agent tools ledger. An agent is not safer merely because it has more tools. It needs checkpoints that can deny, guide, confirm or escalate actions before they execute.
In that architecture, the Jev AI model is a checkpoint with measurable uncertainty, while the agent remains responsible for the broader plan.
The market is copying the interface, not just the model
Jev’s viral launch created attention, but the more durable signal is that other infrastructure companies are adopting the same broad idea. Cloudflare introduced Clef and Clef-flash as open-source decision models, with Apache 2.0 weights on Hugging Face. Its announcement describes bounded outputs, probabilities and workflow integration as the category’s central features, while also noting that Clef adds image input and a larger context window than Jev’s current text-only model.
AWS’s Strands team released Strands Decider 2B as a small open-source model for local experimentation. Its published use cases include model routing, tool selection, evaluations, guardrails, memory and context management. The team reports median local decision latency around 115 milliseconds on an RTX 3090 and around 153 milliseconds for small tasks on an M3 MacBook; those are their measurements on specific hardware, not a universal benchmark.
OpenAI now documents a Decisions API with predicates, choices and scores. That matters because it turns the idea into a platform pattern rather than a single startup’s terminology. The competitive question will shift from “Who invented decision models?” to “Which model and workflow combination is accurate, calibrated, cheap, portable and easy to govern for this job?”
The rise of the Jev AI model category also changes the buyer’s vocabulary. Teams can now ask whether they need generation, reasoning, retrieval or a bounded decision instead of treating every AI requirement as a request for a larger chat model.
For developers, this is good news. The interface is becoming easier to compare. For vendors, it creates pressure to publish decision-specific evaluations instead of relying on general chat benchmarks. For businesses, it creates a new procurement question: is the model available only as a hosted service, or can the same decision layer run locally when the data is sensitive or the network is unreliable?
What Jev means for AI builders now
The immediate opportunity is not to put Jev everywhere. It is to stop using a general LLM as a universal hammer.
A solo developer can use a decision model to classify inbound leads, filter comments, route support requests or decide whether an automated response needs review. A product team can place one between retrieval and generation to check grounding or rank candidates. An AI operations team can use it as a low-latency guardrail before an agent selects a tool. A larger organization can use the same pattern to measure where uncertainty accumulates instead of hiding every decision inside a long generated answer.
Filipino developers, BPO teams and global product builders should pay particular attention to language coverage and privacy. English-first performance does not automatically transfer to Tagalog, Cebuano, Arabic or mixed-language customer data. A hosted API may also be unsuitable for a workflow that cannot send records outside its approved processing environment. The correct test is not a viral demo; it is a labeled sample from the exact workflow, with the actual languages, policies and failure costs.
For practical AI users, the Jev AI model is worth testing as a component, not adopting as a slogan.
Our GPU, TPU and NPU explainer looked at the hardware choices underneath AI services. Jev adds a different systems lesson: efficiency is also a function of the output contract. If an application only needs a bounded decision, generating a page of prose is wasted work no matter how powerful the accelerator is.
The deeper opportunity is composability. A well-designed AI product will not have one giant model making every decision. It will combine code for certainty, a decision model for bounded judgment, a generative model for language and a human for accountability. Jev is an early demonstration of that division of labor.
The Jev AI model is therefore best understood as one layer in a system, not the system itself.
What to watch next
Four developments will determine whether decision models become infrastructure or remain a short-lived model category.
First, portability. Developers will want Jev-compatible interfaces that let them compare a hosted model, an open local model and a vendor-specific model without rebuilding the workflow. Cloudflare and AWS are already pushing in that direction.
Second, evaluation. Accuracy is only one metric. Production teams need calibration, abstention quality, language coverage, latency under load, cost per decision and performance under adversarial input. A model that is 99% accurate but overconfident on the 1% of cases that matter most can still be the wrong choice.
Third, governance. When a probability triggers a real action, someone must own the threshold, the audit trail, the rollback path and the data-handling policy. “The AI decided” is not an acceptable control description.
Fourth, task design. The best results will come from teams that decompose work carefully. Jev is not a shortcut around product thinking. Its central lesson is that many AI problems become more reliable when the open-ended part is separated from the bounded judgment and the exact computation.
Jev therefore deserves attention, but not because every application needs another model. It deserves attention because it makes a neglected design choice visible. AI does not have to be a chatbot or a rigid rule. It can be a fast, probabilistic decision component inside a larger system—provided builders respect what it can and cannot know.
The Jev AI model’s long-term importance will be decided by the quality of those surrounding systems, not by the launch demo alone.
Frequently Asked Questions About the Jev AI Model
What is the Jev AI model?
The Jev AI model is TypeSafe AI’s hosted System One model. It evaluates a state against typed questions and returns structured choices, rubric scores or probabilities instead of free-form text.
Is Jev a large language model?
Jev is not a conventional text-generating LLM interface. It understands natural-language input but is trained and served to make bounded, structured decisions that software can consume directly.
What can Jev be used for?
Jev can be used for routing, classification, moderation, scoring, grounding checks, agent guardrails, tool selection and other workflows with a defined answer space. It should not be used for tasks that require open-ended writing or code generation.
Does Jev generate text?
No. Jev does not generate ordinary text replies or code. Pair it with a generative model or deterministic templates when the application needs an explanation, a response or a newly written artifact.
Does Jev provide reliable confidence scores?
Jev returns probabilities and confidence signals designed for calibrated decisions. Calibration describes performance across groups of predictions; it does not guarantee that an individual prediction is correct. Teams should tune thresholds on their own labeled data.
Is Jev available to run locally?
TypeSafe’s official model reference describes Jev as a hosted API and does not present Jev 1.13.0 as an open-weight local model. Open-source alternatives such as Cloudflare Clef and AWS Strands Decider are separate projects.
What are Jev’s main limitations?
TypeSafe documents weaknesses in arithmetic, counting, date comparison, complex indirection, irrelevant context, adversarial content and text generation. Jev 1.13 also accepts text-based input rather than images, audio or video.
Should a business replace its LLM with Jev?
No blanket replacement is justified. A business should test Jev on narrow, repeatable decisions and use it alongside code, generative models and human review. The right choice depends on accuracy, calibration, language coverage, privacy, latency and the cost of errors.
Sources and methodology
This article was researched from the public Understanding AI overview, TypeSafe AI’s release announcement and documentation, TypeSafe’s model-jaggedness notes, an independent Jev benchmarking preprint, Cloudflare’s Clef announcement, AWS Strands’ Decider release and OpenAI’s Decisions API documentation. Vendor performance and pricing claims are labeled as vendor claims; independent benchmark results are reported with their methodology and limitations.
- Understanding AI: Understanding Jev
- TypeSafe AI: Introducing System One Models & Jev
- TypeSafe documentation: Introduction
- TypeSafe documentation: Models
- TypeSafe documentation: Jev 1.13 jaggedness
- Independent preprint benchmark of Jev
- Cloudflare: Introducing Clef decision models
- AWS Strands: Introducing Strands Decider 2B
- OpenAI Decisions API documentation